
The cost issue of AI in one’s own product is not a model or prompt problem. It is a problem of allocation and architecture. If you can’t clearly allocate AI consumption to each customer, you can neither price, bill or limit it. This is precisely why a surprising number of AI functions fail not in integration, but in operation.
We see this pattern again and again with software providers. The AI feature is integrated in a few days: integrate the SDK, store the API key, send the first requests. That’s enough for the prototype. But as soon as the same feature is up and running for many customers, the questions come that no one asked before:
Which customer incurs which costs? What budget applies per customer, feature or key? How is consumption passed on? And what happens if a single customer exhausts the model deployment limits?
These questions all hinge on a single thing: a resilient consumption allocation per customer. This is exactly where token control comes in. In this article, we go through the three consequences that arise from this: the monetization of AI functions in one’s own product, billing to one’s own customers, and governance over limits and access.
Token control as an AI gateway
Token Control is an AI gateway for software providers. It sits between your application and the connected AI providers. Token Control supports common providers such as Azure AI Foundry, Azure OpenAI, Google Gemini, Mistral, Meta and Anthropic. Your software continues to send its requests as before, and Token Control takes care of routing, consumption recording and budget checking in the background.
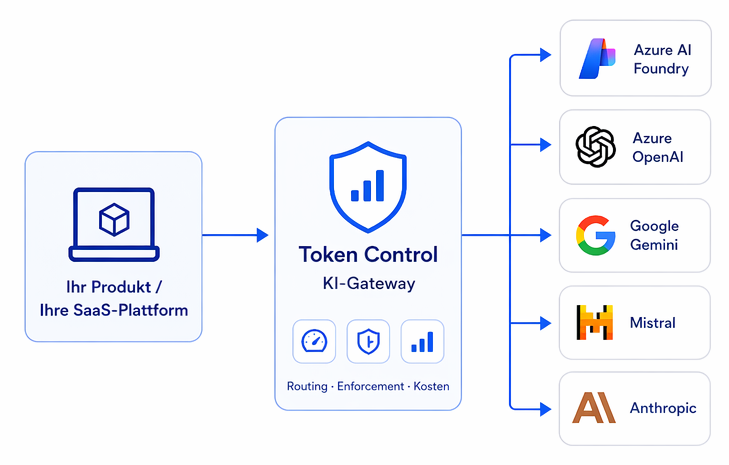
The decisive mechanism is not routing, but consumption-specific allocation. Token control maps your product structure: your customers, including individual users or features, and associated API keys that send the requests and cause the costs. Only this hierarchy solves the problem from the introduction. If you can assign consumption at this level, you have the basis for everything else.

Token control is the measurement, enforcement and cost allocation layer. The commercial decision as to which customer is allowed to use which AI feature in which plan defines the license or entitlement level of your product. Token Control provides the data basis and the hard enforcement on which this level is based. This separation is the reason why Token Control easily fits into existing product and license architectures.
Monetization of AI functions in your own product
Any packaged or usage-based pricing needs a native enforcement size before it works. With token control, this is a budget in euros per customer or feature, measured down to the token and enforced hard before costs are incurred. This is exactly what AI credit packages and tiers are based on. Without this size, you sell an AI function blindly and bear the full cost risk yourself.
A concrete example: A software provider offers its customers three AI credit packages: Small, Medium, Large. “Credit” is the customer-friendly abstraction. Technically, each package corresponds to a monthly limit in euros per customer, created via the Token Control Management API. Once the package is used up, the next request is blocked before uncontrolled costs are incurred.
Token Control does not know silent overspend. If a customer wants more, raise the limit in your product via API, for example when switching from medium to large. This is a deliberate, logged action of your product:
PUT https://mgmt-api.tokencontrol.ai/api/management/consumption/update
Content-Type: application/json

{
  "id": "",
  "name": "Kunde ACME",
  "monthlyLimit": 400.00,
}
This means that you sell a clear package instead of an open cost bet, and your margin is calculable in the package price. The package definition and the factor between credit and euro remain your pricing decision. Token control makes it measurable and enforces the resulting upper limit.
Billing of AI functions to your own customers
Would you like to bill your customers’ AI consumption on a token-by-token basis? With a direct AI provider connection, consumption is only visible at the subscription or resource level, not per customer. This is exactly what makes clean rebilling impossible.
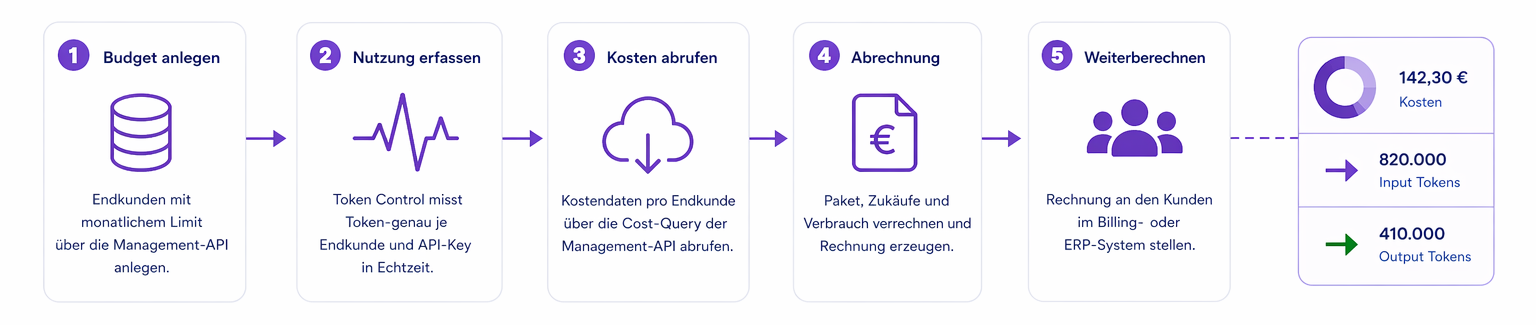
Billing runs programmatically via the Management API. The lifecycle looks like this: You create the customer with a budget, the gateway measures the token consumption per customer and API key, and for the billing run, you retrieve the consumption and cost data per customer via the Token Control Management API.
POST https://mgmt-api.tokencontrol.ai/api/management/cost/query
Content-Type: application/json

{
  "cloudControlId": "",
  "startTime": "2026-06-01T00:00:00Z",
  "endTime": "2026-06-30T23:59:59Z",
  "includeChildren": true
}
The answer provides the costs in the respective currency as well as input and output tokens for each entity:
{
  "costData": [
    {
      "consumptionEntityCloudControlId": "",
      "cost": 142.30,
      "currency": "EUR",
      "inputTokens": 820000,
      "outputTokens": 410000
    }
  ]
}
Back to the example. At the end of the month, your billing run retrieves the cost data per customer via the management API, bills the package as a flat rate plus any additional purchases and automatically generates the invoice item in your billing or ERP system. No manual reconciliation, no discussion with the customer about a number that no one can prove. The same data is available for internal evaluations in the portal and via the API.
Invoicing and contract logic remain in your billing or licensing system. Token Control provides the data and enforces the limits.
Governance and limitations
As soon as AI functions are delivered productively to customers, a pure API connection of the LLM models is no longer sufficient. They must be able to understand how AI is used in the product, what costs are incurred and which rules apply per customer or feature. We have described in more detail elsewhere why AI costs arise in seconds and classic cost management is not sufficient for this.
Token Control provides a central governance layer for this. Budget enforcement takes effect in real time: If a limit is reached, the request is blocked before further costs are incurred. Cost control thus takes place not only during reporting, but during ongoing operation. TPM limits, i.e. tokens per minute, can also be used to prevent a single customer or agent from dominating the shared capacity.
Not every customer should automatically use every model, provider or deployment? Model and deployment approvals can be defined centrally, and API keys can be managed separately for each customer or feature. For operations and support teams, this creates traceability: Why was a request rejected, which model causes the highest consumption, what anomalies occur over time. Each request is documented via a correlation ID with token consumption, model deployment, timestamp and status, while prompts and responses are not stored. Token control provides the technical basis for the necessary transparency and compliance. This is also the case for the EU AI Act.
Integration into existing setups
The technical hurdle is low. In many cases, only the endpoint and API key of your existing integration will change. The SDK you are using remains unchanged. Here is the example of the Azure OpenAI SDK:
from openai import AzureOpenAI

# Endpoint und Key zeigen jetzt auf Token Control
client = AzureOpenAI(
    azure_endpoint="https://api.tokencontrol.ai/api/v1/azure",
    api_key="",
    api_version="2024-12-01",
)
The Management API is available for automated provisioning. This allows you to create customers, budgets, API keys and deployment assignments directly from your existing onboarding or self-service processes instead of manually maintaining them in the Token Control Portal:
POST https://mgmt-api.tokencontrol.ai/api/management/consumption/create
Content-Type: application/json

{
  "cloudControlId": "",
  "name": "Kunde ACME",
  "type": "Department",
  "parentCloudControlId": "",
  "monthlyLimit": 150.00,
  "threshold": 80
}
Token Control does not exclude an existing API gateway such as Azure API Management, but complements it: The gateway takes care of routing and load balancing, token control takes care of the allocation per customer, budgets and reporting.
Comparison, classification and next step
The following overview compares the direct provider connection with the connection via Token Control:
| Dimension | Direct provider connection | Connection via token control |
|---|---|---|
| Real-time Budget Enforcement | 🔴 | 🟢 |
| Consumption per Request | 🟡 | 🟢 |
| Cost allocation per customer, feature, or custom entity | 🟡 | 🟢 |
| Separation by customer | 🔴 | 🟢 |
| Multi-Provider Routing | 🔴 | 🟢 |
| API key management per customer | 🟡 | 🟢 |
| BYOK | – | 🟢 |
| Billing-ready API data | 🔴 | 🟢 |
Back to the initial thesis: AI is quickly integrated, operations are decisive, and this depends on reliable consumption allocation. Token Control provides this foundation for AI monetization, billing, and governance without having to develop a separate billing and governance layer for each customer or feature.